The Rewrite Question: When Fixing Costs More Than Starting Over
Every aging system reaches the point where patching it costs more than replacing it. The rewrite question is a business decision, and it deserves business framing.

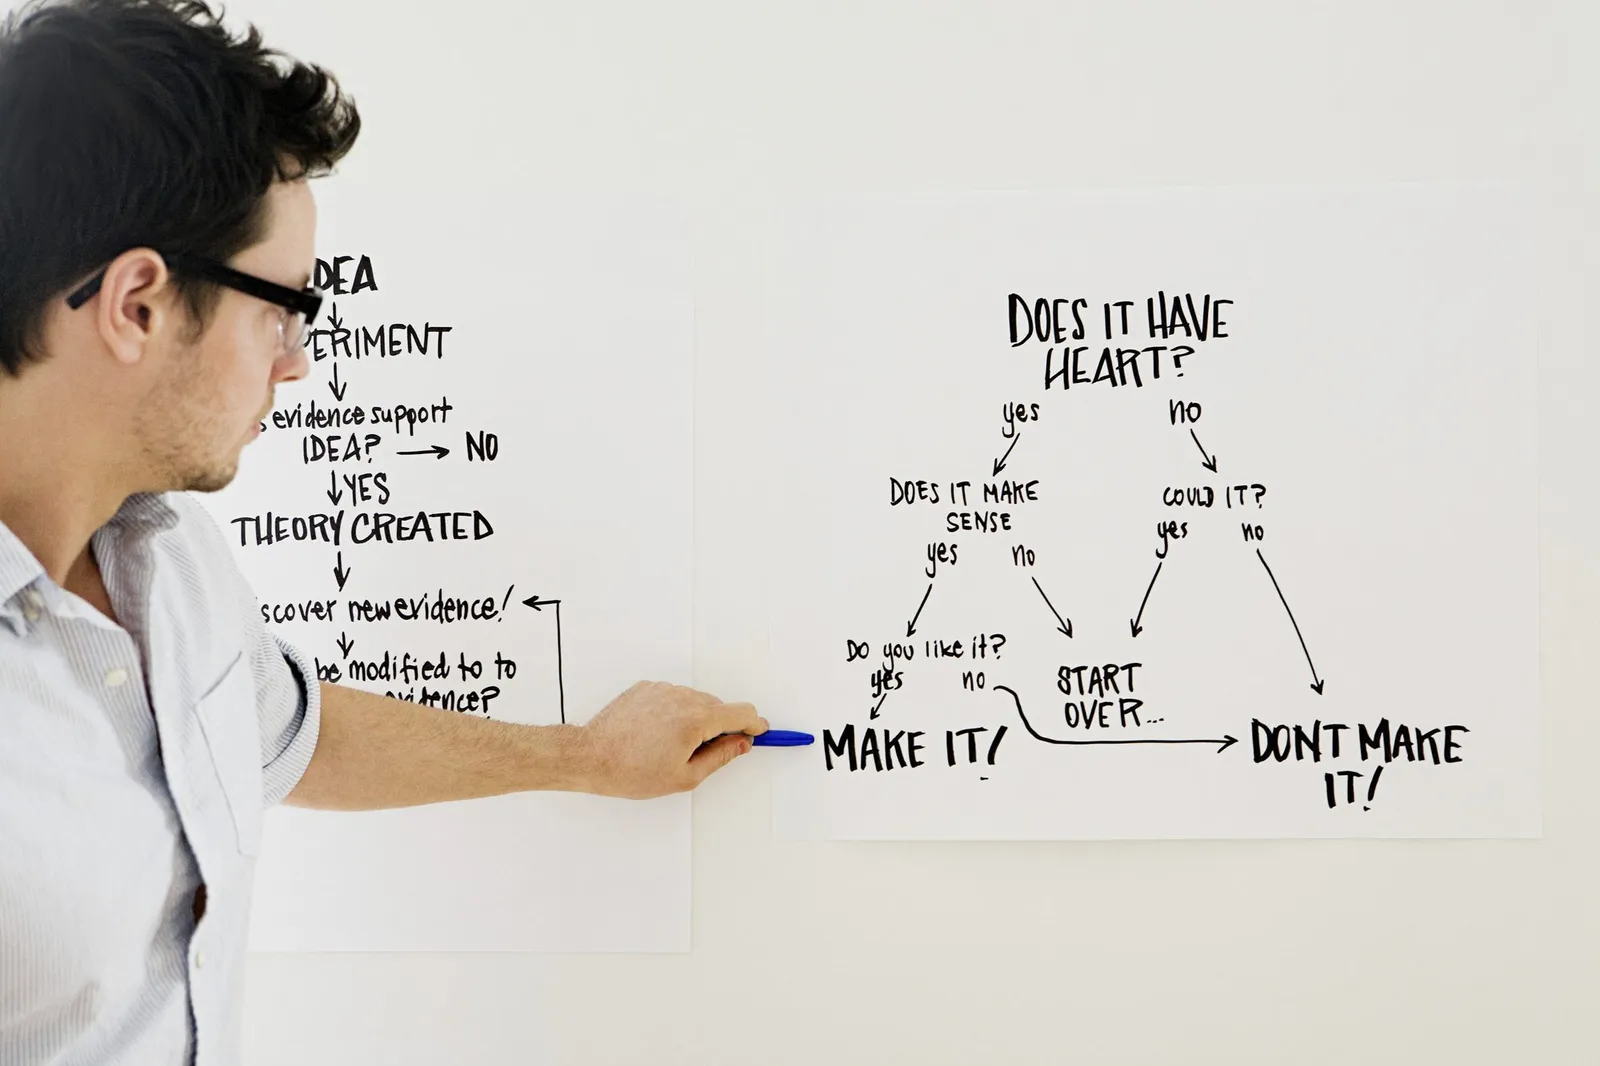
The quoting system is eleven years old. The person who wrote it left in 2021. Every change request comes back with an estimate that makes the operations manager wince, and yet the alternative - replacing it - has been 'next year's project' for four years running.
At some point, every aging system forces the rewrite question: keep paying to maintain and patch, or pay once to replace. Technologists argue about this in terms of elegance. The argument that matters is economic and operational: which path costs less over three years, counting risk?
That framing makes the question legible to the people who fund it, and it keeps the company from the two classic mistakes: rewriting too early out of frustration, and repairing too long out of fear.
TLDR
The rewrite question is economic: compare three-year costs of both paths, including risk.
Repair costs hide in slow changes, workarounds, and the one person who understands the system.
Rewrite costs hide in data migration, retraining, and the first year's lost features.
The risk column often decides it: an unpatchable system is a rewrite with a deadline attached.
Decide with a date and a trigger, not a mood.
The honest cost of keeping it
The repair path looks cheap because its costs arrive in small invoices. Count them properly for one year: the maintenance retainer, the change requests priced like custom development, the workarounds staff build in spreadsheets, the hours lost to slowness and restarts.
Then count the invisible line: key-person risk. When exactly one contractor understands the system, every year of delay is a bet on that person's availability and memory. Companies rarely price this until the day it fails.
The one-page view of these costs is what a technical debt register makes visible, and it turns a vague engineering complaint into a line of business arithmetic.
The honest cost of replacing it
The rewrite path looks expensive because its costs arrive in one number. That number is also routinely understated, and the omissions are predictable: data migration from the old system, the parallel-running period, retraining, and the features nobody documented that the old system quietly had.
The useful rule of thumb from practitioners is to take the build estimate and add the migration and the first year of adjustment explicitly, as their own lines. A rewrite that still wins after honest loading is a real winner.
The replacement decision framework in the go-no-go analysis for legacy replacement is the same discipline from the other direction: what has to be true before the switch gets flipped.
The risk column that breaks ties
When the cost columns are close, the risk column decides. Can the old system still be patched when the next serious vulnerability arrives? Does it still talk to the systems around it without custom glue? Can the company pass a customer's security review while running it?
This fictional example shows the comparison that settled one company's four-year debate. It is an illustration, not a prescription.
| Repair (3 yrs) | Replace (3 yrs) | |
|---|---|---|
| Direct cost | $210k maintenance + changes | $320k build + migration |
| Staff workaround time | ~$40k/yr | ~$10k/yr after yr 1 |
| Patchable going forward | No | Yes |
| Key-person dependency | High | Low |
The risk rows turned a close call into a clear one: the cheaper path was the one that could no longer be defended.
Decide with a trigger, not a mood
The worst version of this decision is made in frustration after an outage, or deferred again in relief after a quiet quarter. The better pattern is a standing trigger, agreed in advance: when annual maintenance exceeds a set fraction of replacement cost, or when a patch cannot be applied, the rewrite evaluation starts automatically.
That converts an emotional, recurring argument into a planned review with known inputs. The system stops being a sore subject and becomes a line item with a date on it.
For the board, the question that keeps this honest is simple: for our most fragile system, what is the trigger, and has anyone checked it this year?
The related discussion of technical debt register is worth your time alongside this one. The related discussion of go-no-go analysis for legacy replacement is worth your time alongside this one.
Frequently asked questions
Isn't a rewrite always riskier than keeping what works?
It carries delivery risk, yes - new systems arrive with their own defects. But 'what works' often means 'what has not failed yet,' and the risk comparison is between a managed, scheduled transition and an unmanaged, unscheduled one.
Who should make the rewrite call?
The business owner of the process the system serves, with IT's honest numbers in front of them. It fails when made purely as a technology preference or purely as a budget reaction.
What about a middle path, wrapping the old system?
Sometimes real: a modern front end on an old core buys time. Treat it as a dated decision too - a wrapper extends life, it does not remove the underlying question, so give it its own trigger for review.
A Defensible Next Step
Pick your oldest business-critical system and ask for the one-year repair ledger: maintenance, changes, workarounds, and the name of everyone who truly understands it. That list usually ends the four-year debate in one meeting. Book a Decision-Clarity Call if you want the comparison built properly.
Get Board-Ready on AI and Cyber Risk
A 30-minute call. No charge. You'll leave with a clear read on where your oversight stands and what to do about it.
Written by Tyson Martin, NACD.DC
Chief Trust, Security & AI Officer. CISO of record at MIO Partners; former CISO & CTO at Lumber Liquidators and Orvis; advisor to 200+ Fortune 500 boards and C-suites at AWS.
See the track record